1. Home
  2. Lyria 3

Lyria 3: Google DeepMind's most advanced AI music generation

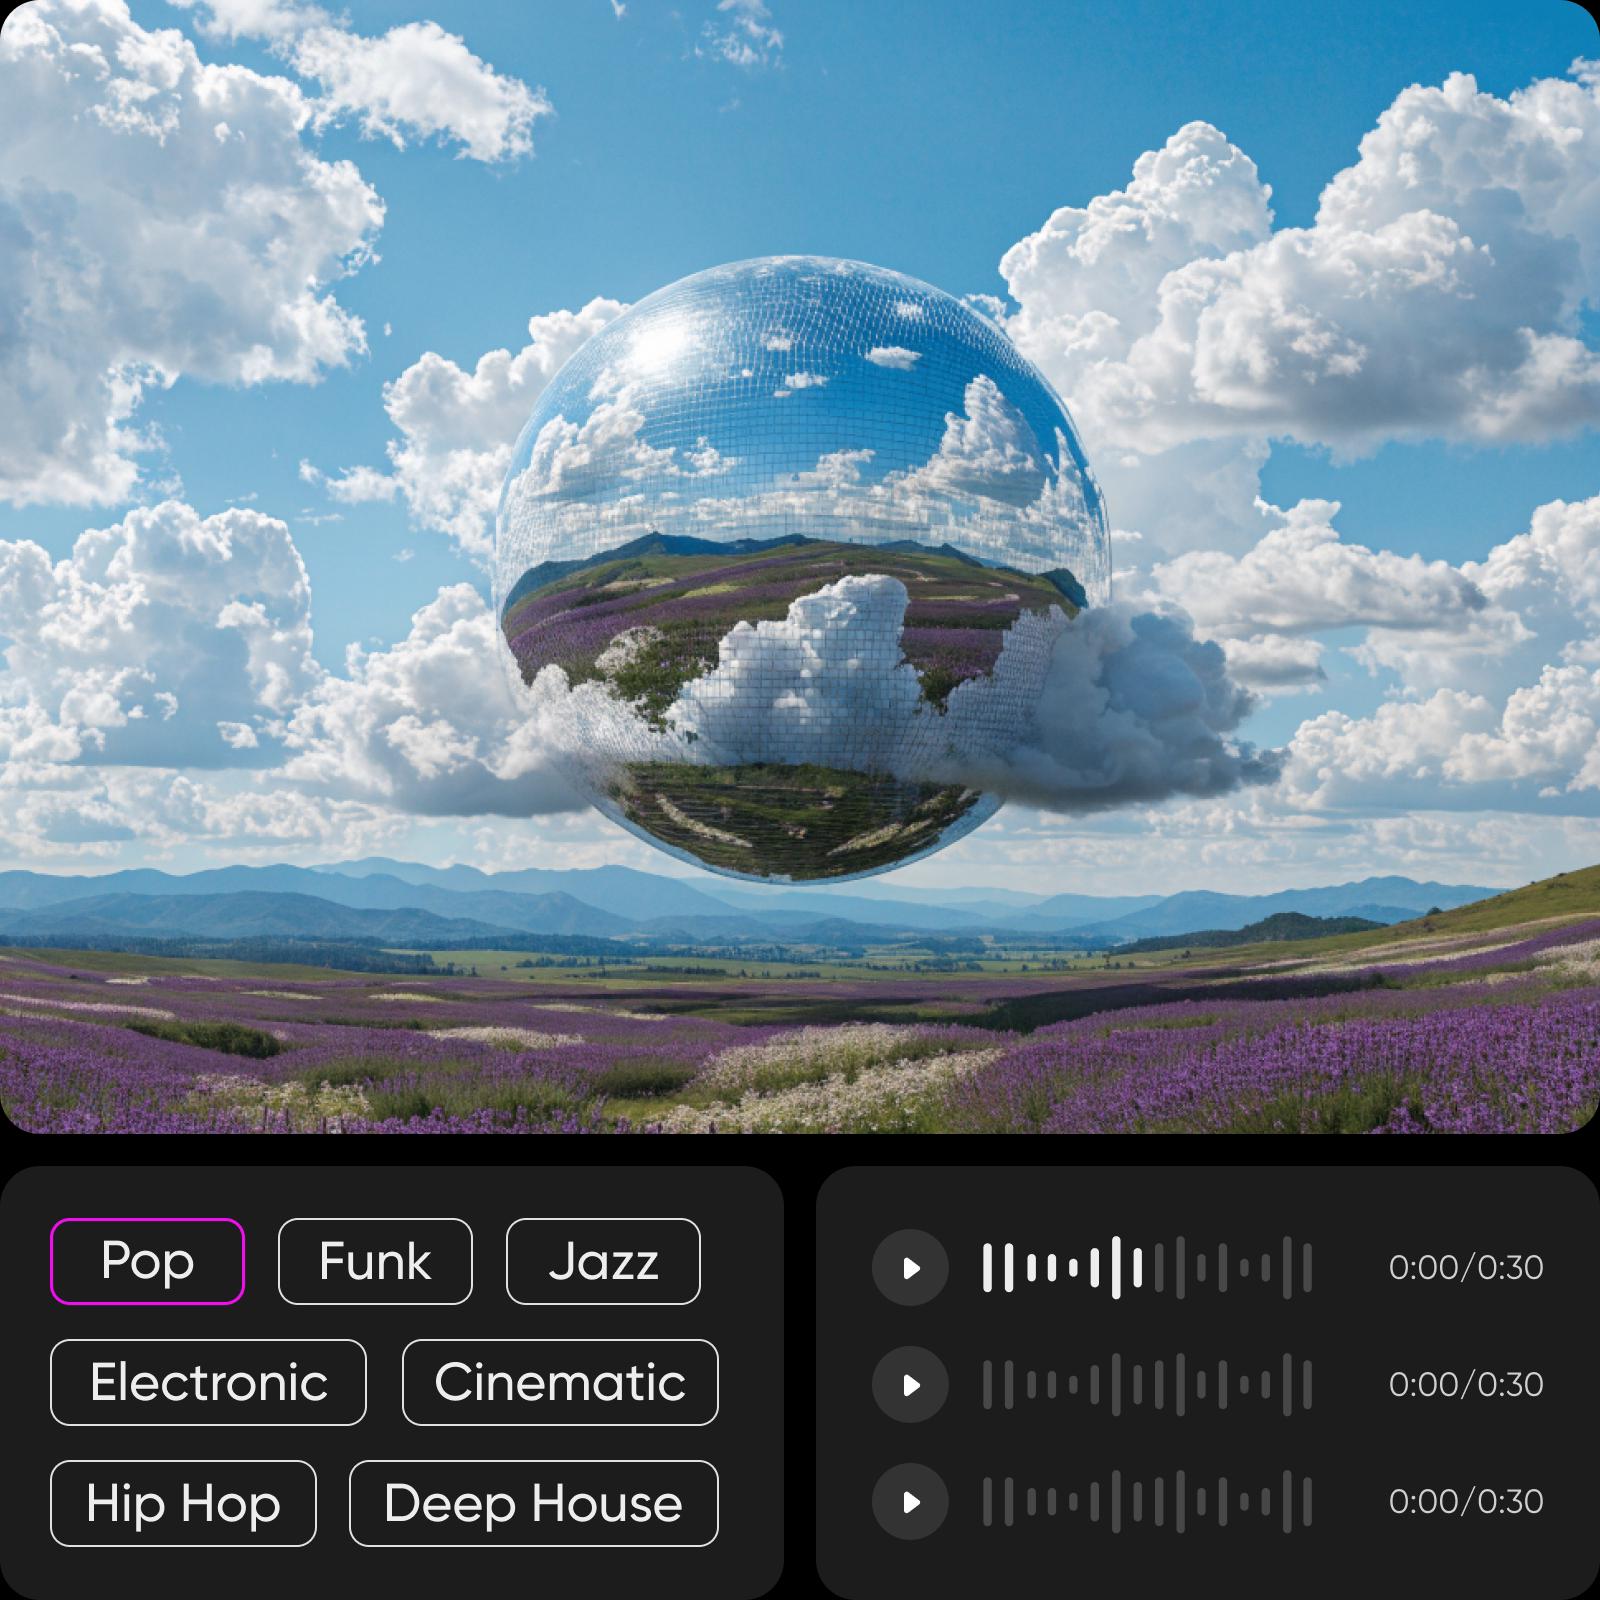
Lyria 3 is Google DeepMind's flagship AI music model, now live on Picsart's AI Playground. It generates full songs up to 3 minutes long with vocals, instrumentation, and professional-grade structure. From text prompts to image-to-music, Lyria 3 creates cohesive tracks across genres - pop, funk, Motown, and more. Every track is watermarked with SynthID for responsible AI identification. Flow integration coming soon.
Start generating
Lyria 3 AI music generation
Discover more from Picsart
DALL-E 3GPT Image 1.5Flux 2 ProIdeogram 3.0 FlashImagen 4.0 UltraRecraft V4Nano Banana ProKling 3.0Luma Ray 2Runway Gen 4Sora 2Veo 3.1Seedance 2.0

Use Picsart anywhere

Install the app, or bring Picsart into the AI workspaces your team already uses.

Use Picsart with

  • ChatGPT / Codex
  • Claude
  • Terminal
  • Cursor
  • OpenClaw
  • Hermes

Download the app

Download on the App StoreGET IT ON Google PlayGet it from Microsoft

Follow Picsart

Pinterest
AICPA SOC

Create

  • AI Image Generator
  • AI Video Generator
  • AI Playground
  • Flow
  • AI Photo Editor
  • AI Video Editor
  • AI Agents
  • Content Library
  • AI Models

Creators

  • Earn with Picsart
  • Earn campaigns
  • Clipping
  • For Brands
  • Video Studio
  • Tutorials
  • Challenges

Connect

  • ChatGPT / Codex
  • MCP setup
  • Command line
  • Developers
  • Google Drive

Business

  • Pricing
  • Enterprise
  • Industries
  • Quicktools

Company

  • Support
  • Careers
  • About us
  • Blog
  • Press Center
Terms of UsePrivacy PolicyInternet-Based AdvertisingCommunity GuidelinesDMCASecurity PolicyAccessibility
© 2026 PicsArt, Inc.

What is Lyria 3?

Lyria 3 is the latest generation of Google DeepMind's music AI, built to understand musicality at a fundamental level - rhythm, arrangement, instrumentation, and vocal performance. The standard Lyria 3 generates polished 30-second tracks with lyrics, vocals, and full instrumentation. Lyria 3 Pro extends this to approximately 3-minute compositions with professional-grade structural awareness - verses, choruses, bridges, and outros that flow naturally. Both versions support multi-language vocals, genre-spanning creation, and detailed prompt control over every musical element. The model was developed with input from producers and musicians including Wyclef Jean and Yung Spielburg.

What you can create with Lyria 3

Describe the music you want - genre, mood, tempo, instruments, vocal style - and Lyria 3 produces a complete track with vocals, instrumentation, and professional structure up to 3 minutes long.

Lyria 3 text to music

Lyria 3 capabilities

Lyria 3 generates music from text prompts — describe anything from "an upbeat birthday tune" to detailed specifications with tempo, key, and instrumentation preferences. Image-to-music converts uploaded images into custom soundtracks that match the visual mood. Define realistic vocal styles and acoustic preferences to shape your sound. Lyria 3 Pro adds full structural control: outline song progression in your prompt, control when lyrics start and end, and produce tracks with verses, choruses, and natural transitions up to 3 minutes. Every output receives SynthID watermarking for AI-origin detection.

How Lyria 3 works inside Picsart

Lyria 3 is now live on Picsart's AI Playground and will be available in Flow soon. Creators can generate AI music directly within Picsart and pair it with videos from AI Video Generator, creating complete audio-visual content without leaving the platform. This connects Lyria 3's music generation with Picsart's image and video tools for a unified creative workflow.

Why creators choose Lyria 3

Lyria 3 stands out as the most musically aware AI model available. It understands song structure, not just sound generation. While other models produce short clips or loops, Lyria 3 Pro generates full 3-minute compositions with natural musical progression. Multi-language vocal support, genre versatility from classical to hip-hop, and prompt-level control over arrangement give creators professional-grade output from a text description. SynthID watermarking ensures responsible use, and the model's training on authorized materials means creators can use outputs confidently. Inside Picsart, it completes the creative loop: generate visuals, generate audio, publish - all in one place.


Lyria 3 FAQ

Lyria 3 is Google DeepMind's most advanced AI music generation model. It creates complete songs with vocals, instrumentation, and professional structure. Lyria 3 produces 30-second tracks, while Lyria 3 Pro generates full compositions up to approximately 3 minutes long.

Lyria 3 generates polished 30-second tracks with lyrics, vocals, and instrumentation. Lyria 3 Pro extends this to approximately 3-minute songs with full structural awareness — verses, choruses, bridges, and natural transitions — with control over when lyrics start and end.

Lyria 3 supports a wide range of genres including pop, funk, Motown, electronic, classical, hip-hop, R&B, rock, jazz, and more. It can also blend genres and create cross-genre compositions from text prompts.

Yes. Lyria 3 generates vocals in multiple languages with customizable vocal styles. You can define realistic vocal preferences, control lyric content, and specify when vocals start and end within a track.

Lyria 3 can convert uploaded images into custom music tracks that match the visual mood and atmosphere of the image. This is useful for creating soundtracks that complement visual content.

Every track generated by Lyria 3 is embedded with SynthID, Google DeepMind's imperceptible digital watermarking technology. This identifies the audio as AI-generated without affecting the listening experience.

Usage terms depend on the platform and access method. Through Picsart's integration, music generated with Lyria 3 can be used for creative and commercial projects subject to Picsart's terms of use.


More AI models to use

Luma Ray 2 AI model for video generation

Luma Ray 2

Luma Ray 2 is a generative AI model optimized for fast, high-fidelity video generation with realistic lighting and motion.

Runway Gen 4 AI model for professional video creation

Runway Gen 4

Runway Gen 4 is a generative AI model designed for professional-grade video creation with fine-grained creative control.

Ideogram 3.0 Flash AI model for fast image creation

Ideogram 3.0 Flash

Ideogram 3.0 Flash is a generative AI model built for fast image creation with accurate text rendering and design precision.

Seedream 4.5 AI model for image generation

Seedream 4.5

Seedream 4.5 is a generative AI model designed for high-quality image generation with advanced visual understanding.

GPT Image 1.5 AI model for text-to-image generation

GPT Image 1.5

GPT Image 1.5 is a multimodal AI model that generates images from text prompts with strong compositional understanding.

Flux 2 Pro AI model for high-resolution image generation

Flux 2 Pro

Flux 2 Pro is a generative AI model optimized for high-resolution image generation with fine detail and creative flexibility.

Kling 3.0 AI model for video generation

Kling 3.0

Kling 3.0 is a generative AI model built for motion-based video creation with advanced control over movement and scene dynamics.

Nano Banana 2 AI model for scalable image creation

Nano Banana 2

Nano Banana 2 is a generative AI model designed for scalable image creation with improved visual quality and speed.

Veo AI model for cinematic video generation

Veo 3.1

Veo is a generative AI model designed for high-quality cinematic video creation and visual storytelling.

Start generating your audio with Lyria 3 AI Model
PricingSave big

Explore more models like Lyria 3

Compare Lyria 3 with other audio models for music, sound, and creative production.

KLKling T2ANew
Text-to-audio clips of 3–10 seconds from a prompt description.CinematicMusic generationSee model
KLKling V2ANew
SASeed Audio MultilingualNew
SASeed AudioNew
GRGrok TTS
Gemini 2.5 Flash TTS
Gemini 2.5 Pro TTS
ELEleven v3
ELEleven Multilingual v2
ELEleven Dialogue v3
ELElevenLabs SFX v2
ELElevenLabs Music v2
KLKling T2ANew
KLKling T2ANew
KLKling T2ANew
KLKling T2ANew
KLKling T2ANew

AI-powered creativity, no limits

Prescott
Try this vibe
Truffle
Try this vibe
Sloane
Try this vibe
Indigo Sphinx
Try this vibe
Paris
Try this vibe
Tofu
Try this vibe
Silver Scarab
Try this vibe
Nugget
Try this vibe
Dumpling
Try this vibe
Woolf
Try this vibe
Extract or generate a matching audio track from an uploaded video.
CinematicMusic generation
See model
Synthesize natural speech in 20 languages — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
Synthesize natural English or Chinese speech — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
Expressive text-to-speech from xAI Grok with multilingual support.
Music generation
See model
Google Gemini native text-to-speech with expressive multilingual voices.
Fast generationMusic generation
See model
Premium Gemini TTS with richer expressiveness and multi-speaker support.
Pro qualityMusic generation
See model
Latest voice engine with expanded tone and pacing control.Music generationSee model
Stable multilingual speech across 29+ languages with natural rhythm.Music generationSee model
Generate a multi-speaker conversation — a voice per line — in one take.
Music generation
See model
Create custom sound effects from a text description — up to 30 seconds.Music generationSee model
Generate music with vocals or instrumental from a text prompt.
Music generation
See model
Text-to-audio clips of 3–10 seconds from a prompt description.CinematicMusic generationSee model
KLKling V2ANew
Extract or generate a matching audio track from an uploaded video.CinematicMusic generationSee model
SASeed Audio MultilingualNew
Synthesize natural speech in 20 languages — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
SASeed AudioNew
Synthesize natural English or Chinese speech — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
GRGrok TTS
Expressive text-to-speech from xAI Grok with multilingual support.Music generationSee model
Gemini 2.5 Flash TTS
Google Gemini native text-to-speech with expressive multilingual voices.Fast generationMusic generationSee model
Gemini 2.5 Pro TTS
Premium Gemini TTS with richer expressiveness and multi-speaker support.Pro qualityMusic generationSee model
ELEleven v3
Latest voice engine with expanded tone and pacing control.Music generationSee model
ELEleven Multilingual v2
Stable multilingual speech across 29+ languages with natural rhythm.Music generationSee model
ELEleven Dialogue v3
Generate a multi-speaker conversation — a voice per line — in one take.Music generationSee model
ELElevenLabs SFX v2
Create custom sound effects from a text description — up to 30 seconds.Music generationSee model
ELElevenLabs Music v2
Generate music with vocals or instrumental from a text prompt.Music generationSee model
Text-to-audio clips of 3–10 seconds from a prompt description.CinematicMusic generationSee model
KLKling V2ANew
Extract or generate a matching audio track from an uploaded video.CinematicMusic generationSee model
SASeed Audio MultilingualNew
Synthesize natural speech in 20 languages — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
SASeed AudioNew
Synthesize natural English or Chinese speech — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
GRGrok TTS
Expressive text-to-speech from xAI Grok with multilingual support.Music generationSee model
Gemini 2.5 Flash TTS
Google Gemini native text-to-speech with expressive multilingual voices.Fast generationMusic generationSee model
Gemini 2.5 Pro TTS
Premium Gemini TTS with richer expressiveness and multi-speaker support.Pro qualityMusic generationSee model
ELEleven v3
Latest voice engine with expanded tone and pacing control.Music generationSee model
ELEleven Multilingual v2
Stable multilingual speech across 29+ languages with natural rhythm.Music generationSee model
ELEleven Dialogue v3
Generate a multi-speaker conversation — a voice per line — in one take.Music generationSee model
ELElevenLabs SFX v2
Create custom sound effects from a text description — up to 30 seconds.Music generationSee model
ELElevenLabs Music v2
Generate music with vocals or instrumental from a text prompt.Music generationSee model
Text-to-audio clips of 3–10 seconds from a prompt description.CinematicMusic generationSee model
KLKling V2ANew
Extract or generate a matching audio track from an uploaded video.CinematicMusic generationSee model
SASeed Audio MultilingualNew
Synthesize natural speech in 20 languages — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
SASeed AudioNew
Synthesize natural English or Chinese speech — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
GRGrok TTS
Expressive text-to-speech from xAI Grok with multilingual support.Music generationSee model
Gemini 2.5 Flash TTS
Google Gemini native text-to-speech with expressive multilingual voices.Fast generationMusic generationSee model
Gemini 2.5 Pro TTS
Premium Gemini TTS with richer expressiveness and multi-speaker support.Pro qualityMusic generationSee model
ELEleven v3
Latest voice engine with expanded tone and pacing control.Music generationSee model
ELEleven Multilingual v2
Stable multilingual speech across 29+ languages with natural rhythm.Music generationSee model
ELEleven Dialogue v3
Generate a multi-speaker conversation — a voice per line — in one take.Music generationSee model
ELElevenLabs SFX v2
Create custom sound effects from a text description — up to 30 seconds.Music generationSee model
ELElevenLabs Music v2
Generate music with vocals or instrumental from a text prompt.Music generationSee model
Text-to-audio clips of 3–10 seconds from a prompt description.CinematicMusic generationSee model
KLKling V2ANew
Extract or generate a matching audio track from an uploaded video.CinematicMusic generationSee model
SASeed Audio MultilingualNew
Synthesize natural speech in 20 languages — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
SASeed AudioNew
Synthesize natural English or Chinese speech — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
GRGrok TTS
Expressive text-to-speech from xAI Grok with multilingual support.Music generationSee model
Gemini 2.5 Flash TTS
Google Gemini native text-to-speech with expressive multilingual voices.Fast generationMusic generationSee model
Gemini 2.5 Pro TTS
Premium Gemini TTS with richer expressiveness and multi-speaker support.Pro qualityMusic generationSee model
ELEleven v3
Latest voice engine with expanded tone and pacing control.Music generationSee model
ELEleven Multilingual v2
Stable multilingual speech across 29+ languages with natural rhythm.Music generationSee model
ELEleven Dialogue v3
Generate a multi-speaker conversation — a voice per line — in one take.Music generationSee model
ELElevenLabs SFX v2
Create custom sound effects from a text description — up to 30 seconds.Music generationSee model
ELElevenLabs Music v2
Generate music with vocals or instrumental from a text prompt.Music generationSee model
Text-to-audio clips of 3–10 seconds from a prompt description.CinematicMusic generationSee model
KLKling V2ANew
Extract or generate a matching audio track from an uploaded video.CinematicMusic generationSee model
SASeed Audio MultilingualNew
Synthesize natural speech in 20 languages — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
SASeed AudioNew
Synthesize natural English or Chinese speech — pick a named voice or clone one from a reference audio.Reference inputMusic generationSee model
GRGrok TTS
Expressive text-to-speech from xAI Grok with multilingual support.Music generationSee model
Gemini 2.5 Flash TTS
Google Gemini native text-to-speech with expressive multilingual voices.Fast generationMusic generationSee model
Gemini 2.5 Pro TTS
Premium Gemini TTS with richer expressiveness and multi-speaker support.Pro qualityMusic generationSee model
ELEleven v3
Latest voice engine with expanded tone and pacing control.Music generationSee model
ELEleven Multilingual v2
Stable multilingual speech across 29+ languages with natural rhythm.Music generationSee model
ELEleven Dialogue v3
Generate a multi-speaker conversation — a voice per line — in one take.Music generationSee model
ELElevenLabs SFX v2
Create custom sound effects from a text description — up to 30 seconds.Music generationSee model
ELElevenLabs Music v2
Generate music with vocals or instrumental from a text prompt.Music generationSee model

Understand image model choices

Learn how to compare image models and choose an output.

Compare AI image models side by side on Picsart preview
Image models

Compare AI image models side by side on Picsart

4 minIntermediate
Understand AI credit costs and model pricing on Picsart preview
Image models

Understand AI credit costs and model pricing on Picsart

5 minIntermediate
Create stunning illustrations with AI image models preview
Image models

Create stunning illustrations with AI image models

5 minIntermediate
Generate photorealistic images with AI models preview
Image models

Generate photorealistic images with AI models

5 minIntermediate
See all tutorials

Generate AI visuals with Lyria 3

Pro

Most popular

AI tools for everyday creative work.

$15 $10.5/mo
Billed yearly
You save $54 with yearly
  • Access to all photo & video editing features
  • Advanced background & object removal
  • Parallel video generations with the world's most powerful AI video models
  • Unlimited image generations with Flex.2 Klein
  • 1-tap image enhancer
  • Millions of stock photos & Getty video clips
  • Selection of trendy fonts, text styles & stickers
  • Thousands of premium templates
  • Support for 3+ brand kits
  • Bulk edit up to 50 images at once
  • 100 GB of cloud storage
New features:
  • Auto-generate content from your terminal or agent with the Picsart CLI
  • Use Picsart inside Claude Code, Cursor, and ChatGPT via MCP — coming soon
  • AI agents for multi-step workflows and batch generation — coming soon

Ultra

Most powerful

Heavy AI usage for creators & teams.

$45 $24.5/mo
Billed yearly, per seat
You save $246 with yearly
  • Everything in Pro
  • Early access to advanced AI features
  • Leading AI models to design & automate workflows (Nano Banana, Veo 3, Seedance 2.0 & more)
  • Parallel video generations with the world's most powerful AI video models
  • Unlimited image generations with Flex.2 Klein
  • Support for 10+ brand kits
  • Add team seats
  • Create ad variations and localize
  • Track ads performance
  • 2000 credits for API services
  • Bulk edit up to 100 images at once
  • 300 GB of cloud storage per seat
New features:
  • Auto-generate content from your terminal or agent with the Picsart CLI
  • Use Picsart inside Claude Code, Cursor, and ChatGPT via MCP — coming soon
  • AI agents for multi-step workflows and batch generation — coming soon

Enterprise

Custom AI solutions for large organizations.

Custom credit volume
  • Volume discounts on credit rate
  • On-demand top-ups
Custom
Contact for pricing
  • Access to photo & video editor SDKs
  • Mobile web SDK support
  • Prepaid or pay-as-you-go creative APIs
  • Embed professional-grade editing into your product or workflow
  • Fully configurable editing experience
  • White-label to match your brand
  • Support for built-in marketing, e-commerce & printing use cases
  • Bring your own assets: images, templates & fonts
  • Enterprise-grade security, SLAs & support
  • Dedicated account manager